Cloud Data Ingestion for Azure Blob Storage
This page covers everything you need to sync data from Azure Blob Storage to Braze using Cloud Data Ingestion (CDI): the Azure resources to create, how to connect the source and create a sync in Braze, the file format for each data type, and Azure-specific troubleshooting.
How it works
Azure Blob Storage integrations are event-driven rather than scheduled. When new files are created in the container, an event subscription in Azure Event Grid publishes a Blob Created event to an Azure Storage queue. Braze reads those messages from the queue to ingest the new file.
The integration requires the following resources:
- A storage account with a blob container for data storage
- An Azure Storage queue and an event subscription for new file notifications
- A Microsoft Entra ID service principal that CDI uses to read the container and the queue
Azure definitions
| Term | Definition |
|---|---|
| Storage account | A storage account is the top-level Azure resource that holds both the container CDI reads files from and the queue CDI reads notifications from. |
| Container | A container holds the data files you want CDI to ingest. Containers live inside a storage account. |
| Azure Storage queue | A queue receives new-file notifications from your container. CDI reads and acknowledges messages from this queue to know which files to ingest. |
| Event subscription | An event subscription routes events from your storage account to a destination, using the Azure Event Grid service. You configure it to send Blob Created events to your queue. |
| System topic | A system topic represents the source of the events. Event Grid creates one for your storage account when you add the first event subscription. |
| Service principal | A service principal is a Microsoft Entra ID identity that CDI authenticates as. You create it through an app registration and enter its credentials in Braze. |
| Azure role assignment | A role assignment grants a service principal a set of permissions at a given scope. You assign three built-in roles to the Braze service principal on your storage account. |
Set up Cloud Data Ingestion in Azure
Step 1: Create a container
The container and the queue must live in the same storage account. You can reuse an existing storage account. If you don’t have one yet, go to Storage accounts > + Create in the Azure portal to create it.
- In the Azure portal, go to your storage account, then go to Data storage > Containers.
- Select + Add container and give it a name.
Note the storage account name and the container name. You’ll need both when you configure the source in Braze.
Step 2: Create a queue
- In the same storage account, go to Data storage > Queues.
- Select + Queue and give it a name.
Note the queue name. You’ll need it when you create the sync, and each sync needs its own queue.
Step 3: Create an event subscription
Create an event subscription so that your container tells the queue whenever a file arrives.
- In the same storage account, go to Events, then select + Event Subscription.
- Under Event Subscription Details, enter a Name, and set Event Schema to Event Grid Schema.
- Under Topic Details, review the System Topic Name. If your storage account doesn’t have a system topic yet, enter a name to create one. If it already has one, the field shows that name and can’t be changed. All event subscriptions on a storage account use the same system topic.
- Under Event Types, set Filter to Event Types to Blob Created only. Blob Deleted is also selected by default, so clear it.
- Under Endpoint Details, set Endpoint Type to Storage Queue. The Configure an endpoint link appears after you choose an endpoint type.
- Select Configure an endpoint, then choose the storage account you’re working in.
- Select Select existing queue, then choose the queue you created in step 2.
- Select Select to confirm the endpoint.
- Select Create.
Step 4: Set up authentication
CDI connects to your storage account with the following authentication method:
| Method | How Braze authenticates | What you enter in Braze |
|---|---|---|
| Service principal | Braze authenticates as a Microsoft Entra ID service principal with a client secret. | Tenant ID, Principal ID, and Client Secret |
Service principal
CDI connects to your storage account using a service principal with Microsoft Entra ID authentication. Braze needs the following details to connect:
- Tenant ID (also called directory) for your Azure account
- Principal ID (also called application ID) for the service principal
- Client secret for Braze to authenticate
Registering an application requires permission to create app registrations in Microsoft Entra ID. If you don’t have it, ask an Entra administrator to complete this step and share the credentials with you.
- In the Azure portal, navigate to the Microsoft Entra admin center, and then App Registrations.
- Select + New registration under Identity > Applications > App registrations
- Enter a name, and select
Accounts in this organizational directory onlyas the supported account type. Then, select Register. - Select the application (service principal) you just created, then navigate to Certificates & secrets > + New client secret
- Enter a description for the secret, and set an expiry period for the secret. Then, select Add.
- Note the client secret created to use in the Braze setup.
Azure doesn’t allow unlimited expiry on service principal secrets. Remember to refresh the credentials before they expire to maintain the flow of data to Braze.
We recommend creating a service principal that’s used only for CDI, so its access stays limited to the container and queue you’re syncing. If you already have one set up for a Microsoft Fabric source, you can reuse it, but it then has access to both. Either way, it needs the role assignments in the next step.
Step 5: Assign permissions to the service principal
CDI needs only enough access to read your files and process queue messages. Assign these three built-in roles on the storage account itself, not at the subscription or resource group, because role assignments inherit downward. Don’t assign broader roles such as Storage Blob Data Contributor, Storage Account Contributor, or Owner, which grant write and management permissions that CDI never uses.
- Go to your storage account, then go to Access Control (IAM).
- Select Add > Add role assignment.
- Search for the service principal you created in step 4 by name.
- Assign it the following built-in roles:
- Storage Blob Data Reader: lets CDI read the files in your container.
- Storage Queue Data Reader: lets CDI read the queue itself, so it can find the queue you named on the sync and check its properties.
- Storage Queue Data Message Processor: lets CDI peek, retrieve, and delete messages on your queue.
You can use a custom role instead, as long as it grants only read access to blobs in the container, read access to the queue, and the ability to receive and delete messages on the queue.
If Add role assignment is grayed out, your account can’t assign roles on this storage account. This requires a role such as Owner or User Access Administrator. Ask an Azure administrator to complete this step.
Set up Cloud Data Ingestion in Braze
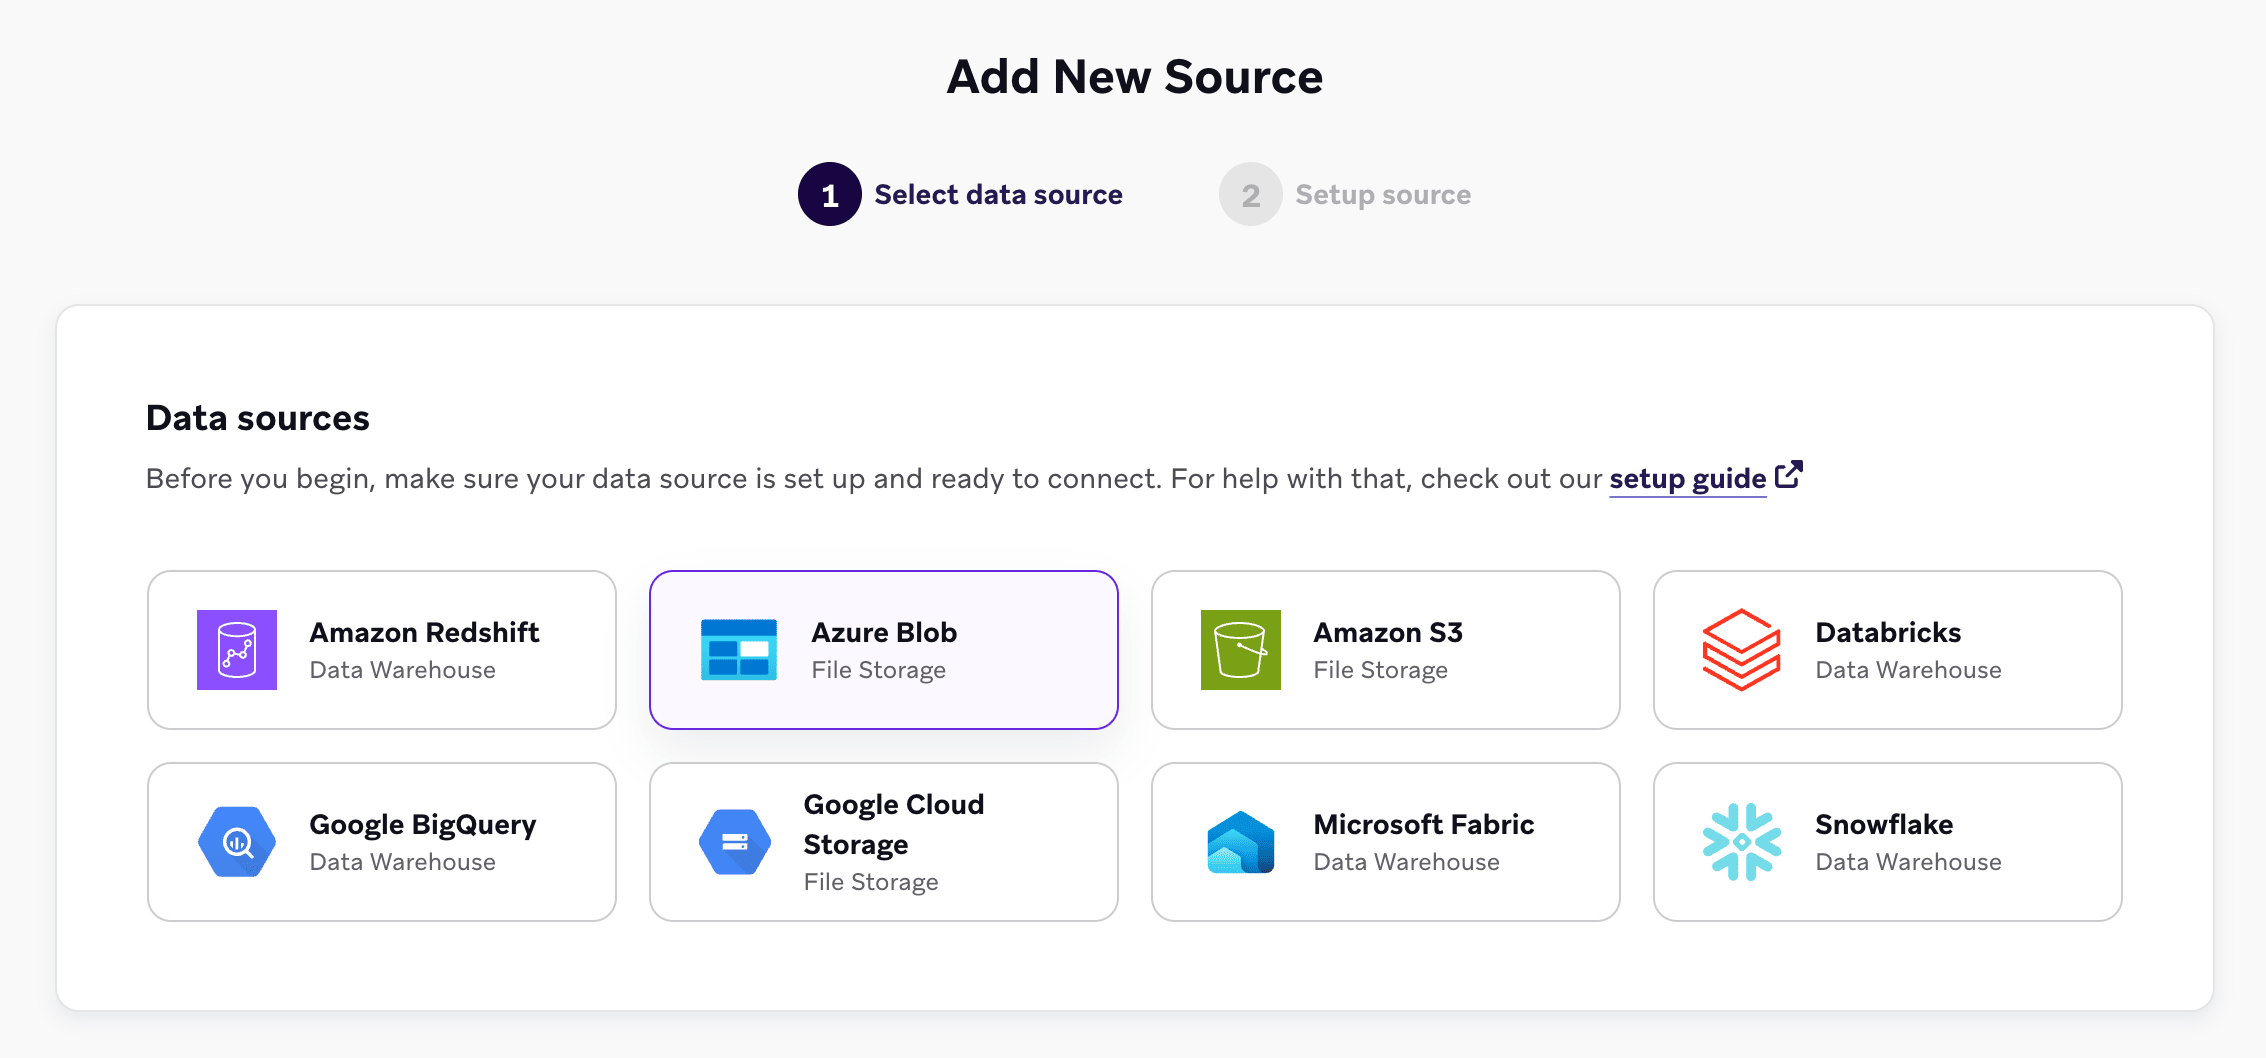
- In Braze, go to Data Settings > Cloud Data Ingestion > Sources, select Add data source, and then select Azure Blob.
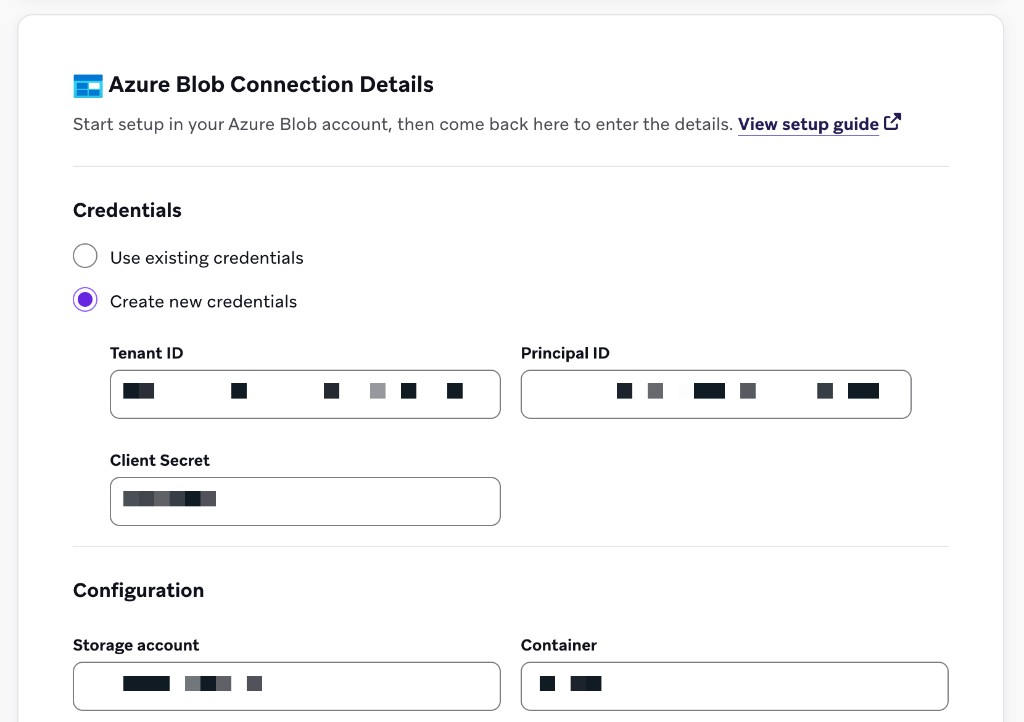
- Complete the Azure Blob Connection Details fields:
-
Credentials: the fields for the authentication method you set up in Step 4. Enter Tenant ID, Principal ID, and Client Secret.
-
Configuration: Storage account and Container
-
- Select Test connection, then select Connect to Source.
- Create a sync. Go to Data Settings > Cloud Data Ingestion > Syncs and select Create data sync.
- On Configurations, choose a sync name, select your Azure Blob source, and select a Data Type (such as User Attributes, Custom Events, Purchase Events, Catalog, or Delete Users).
- On Data definition, specify the following:
- Storage queue name: the queue you created in Step 2. Each sync needs its own queue (see Syncing a folder in a shared container).
- Folder path (Optional): a path prefix within the container
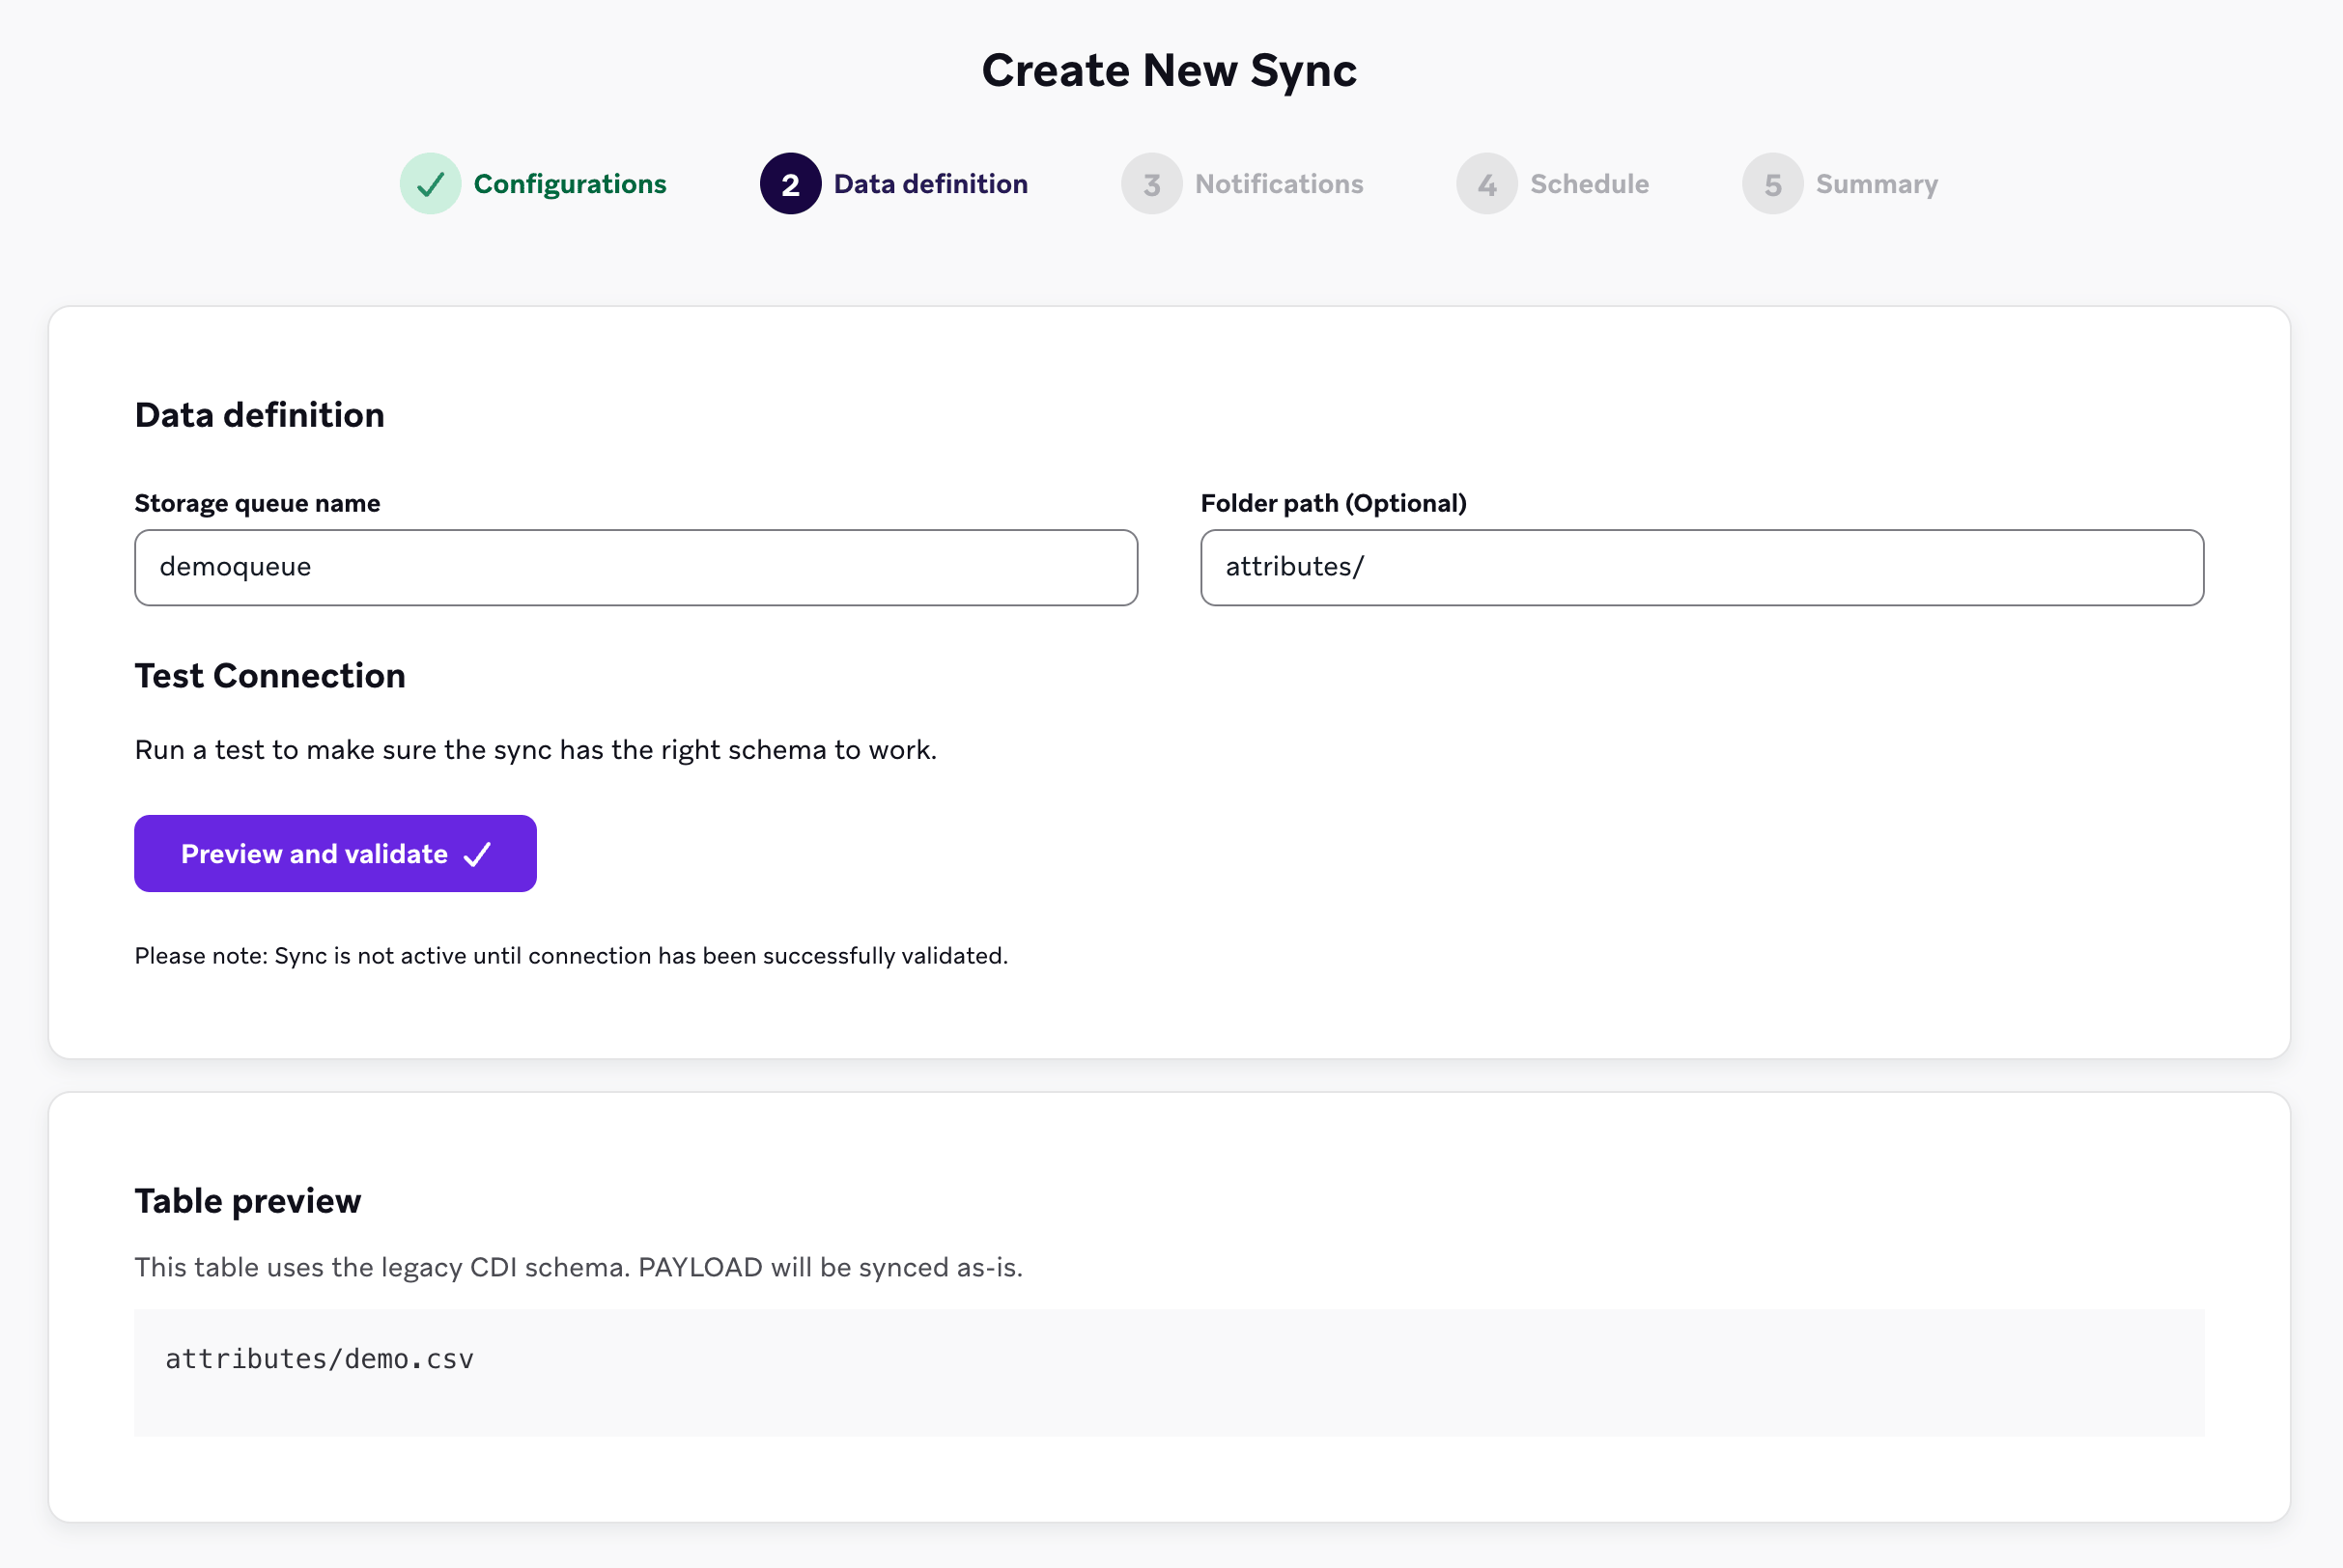
- Select Preview and validate to confirm CDI can reach the queue and list the files available to ingest. A successful test lists existing files in the container, but those files aren’t synced automatically. The sync isn’t active until the connection validates successfully.
- On Notifications, add contact email addresses for error notifications.
- Schedule has no options for file storage syncs. Azure Blob Storage syncs are event-driven, so CDI ingests new files as they’re uploaded.
- Review the Summary, then select Create sync.
Syncing a folder in a shared container
You can reuse one container across multiple syncs, but each sync needs its own storage queue and its own folder.
Two syncs can’t use the same storage queue. If you enter a queue that another sync already uses, CDI flags it and links to the existing sync.
For each folder you want to sync in a shared container:
- Create a queue for that folder, as in Step 2.
- Create an event subscription that sends the container’s Blob Created events to that queue, as in Step 3.
- When you create the sync in Braze, enter that folder’s Storage queue name and set Folder path (Optional) to the folder prefix, such as
attributes/. CDI only ingests files whose path starts with that prefix.
Required file formats
Cloud Data Ingestion supports JSON, CSV, and Parquet files. The required columns depend on the data type. Braze doesn’t enforce any additional filename requirements beyond what’s enforced by your file storage provider. Filenames should be unique, and appending a timestamp helps ensure uniqueness.
Unlike with data warehouse sources, the UPDATED_AT column is neither required nor supported for file storage syncs.
For examples of all supported file types, see the sample files in braze-examples.
Select the tab for the data type you want to sync.
Each row requires exactly one user identifier and a PAYLOAD column. A source file may contain rows with different identifier types, but each individual row should only use one.
| Identifier | Description |
|---|---|
EXTERNAL_ID |
This identifies the user you want to update. This should match the external_id value used in Braze. |
ALIAS_NAME and ALIAS_LABEL |
These two columns create a user alias object. alias_name should be a unique identifier, and alias_label specifies the type of alias. Users may have multiple aliases with different labels, but only one alias_name per alias_label. |
BRAZE_ID |
The Braze user identifier. This is generated by the Braze SDK, and new users cannot be created using a Braze ID through Cloud Data Ingestion. To create new users, specify an external user ID or user alias. |
EMAIL |
The user’s email address. If multiple profiles with the same email address exist, the most recently updated profile is prioritized for updates. If you include both email and phone, Braze uses the email as the primary identifier. |
PHONE |
The user’s phone number. If multiple profiles with the same phone number exist, the most recently updated profile is prioritized for updates. |
The PAYLOAD column contains a JSON string of the fields you want to sync to the user in Braze, following the user attributes object format.
JSON example
{"external_id":"s3-qa-0","payload":"{\"name\": \"GT896\", \"age\": 74, \"subscriber\": true, \"retention\": {\"previous_purchases\": 21, \"vip\": false}, \"last_visit\": \"2023-08-08T16:03:26.600803\"}"}
{"external_id":"s3-qa-1","payload":"{\"name\": \"HSCJC\", \"age\": 86, \"subscriber\": false, \"retention\": {\"previous_purchases\": 0, \"vip\": false}, \"last_visit\": \"2023-08-08T16:03:26.600824\"}"}
{"external_id":"s3-qa-2","payload":"{\"name\": \"YTMQZ\", \"age\": 43, \"subscriber\": false, \"retention\": {\"previous_purchases\": 23, \"vip\": true}, \"last_visit\": \"2023-08-08T16:03:26.600831\"}"}
CSV example
external_id,payload
s3-qa-load-0-d0daa196-cdf5-4a69-84ae-4797303aee75,"{""name"": ""SNXIM"", ""age"": 54, ""subscriber"": true, ""retention"": {""previous_purchases"": 19, ""vip"": true}, ""last_visit"": ""2023-08-08T16:03:26.598806""}"
s3-qa-load-1-d0daa196-cdf5-4a69-84ae-4797303aee75,"{""name"": ""0J747"", ""age"": 73, ""subscriber"": false, ""retention"": {""previous_purchases"": 22, ""vip"": false}, ""last_visit"": ""2023-08-08T16:03:26.598816""}"
Every line in your source file must contain valid JSON, or the file is skipped.
Custom events use the same user identifier columns as user attributes. The PAYLOAD column follows the events object format.
{"external_id":"s3-qa-0","payload":"{\"app_id\": \"YOUR_APP_ID\", \"name\": \"view-206\", \"time\": \"2024-04-02T14:34:08\", \"properties\": {\"bool_value\": false, \"preceding_event\": \"unsubscribe\", \"important_number\": 206}}"}
{"external_id":"s3-qa-1","payload":"{\"app_id\": \"YOUR_APP_ID\", \"name\": \"view-206\", \"time\": \"2024-04-02T14:34:08\", \"properties\": {\"bool_value\": false, \"preceding_event\": \"unsubscribe\", \"important_number\": 206}}"}
Every line in your source file must contain valid JSON, or the file is skipped.
Purchase events use the same user identifier columns as user attributes. The PAYLOAD column follows the purchases object format.
{"external_id":"s3-qa-0","payload":"{\"app_id\": \"YOUR_APP_ID\", \"product_id\": \"product-11\", \"currency\": \"BSD\", \"price\": 8.511527858335066, \"time\": \"2024-04-02T14:34:08\", \"quantity\": 19, \"properties\": {\"is_a_boolean\": true, \"important_number\": 40, \"preceding_event\": \"click\"}}"}
{"external_id":"s3-qa-1","payload":"{\"app_id\": \"YOUR_APP_ID\", \"product_id\": \"product-11\", \"currency\": \"BSD\", \"price\": 8.511527858335066, \"time\": \"2024-04-02T14:34:08\", \"quantity\": 19, \"properties\": {\"is_a_boolean\": true, \"important_number\": 40, \"preceding_event\": \"click\"}}"}
Every line in your source file must contain valid JSON, or the file is skipped.
Catalog files use different identifiers than user data files. Before you create a catalog sync, create the target catalog in Braze. For the full catalog workflow, see Sync and delete catalog data.
| Column | Required | Description |
|---|---|---|
ID |
Yes | The unique identifier for the catalog item. Used to create, update, or delete the item in Braze. |
PAYLOAD |
Yes | A JSON string of the catalog fields and values to sync. Must match the schema of your catalog in Braze. |
DELETED |
No | When true, the catalog item with the matching ID is removed from the catalog in Braze. Omit this column or set to false for create or update operations. |
JSON example
{"id":"85","payload":"{\"product_name\":\"Product 85\",\"price\":85.85}"}
{"id":"86","payload":"{\"product_name\":\"Product 86\",\"price\":86.86}"}
{"id":"1","payload":"{\"product_name\":\"Product 1\",\"price\":1.01}","deleted":true}
CSV example with the DELETED column
ID,PAYLOAD,DELETED
85,"{""product_name"": ""Product 85"", ""price"": 85.85}",false
86,"{""product_name"": ""Product 86"", ""price"": 86.86}",false
1,"{""product_name"": ""Product 1"", ""price"": 1.01}",true
CSV example without the DELETED column
ID,PAYLOAD
85,"{""product_name"": ""Product 85"", ""price"": 85.85}"
86,"{""product_name"": ""Product 86"", ""price"": 86.86}"
Canvas triggers power zero-copy personalization. For the destination Canvas setup and considerations, see Zero-copy personalization.
| Field | Required | Description |
|---|---|---|
EXTERNAL_ID |
Yes, one of external_id or alias_name and alias_label |
This identifies the user you want to update. This should match the external_id value used in Braze. |
ALIAS_NAME and ALIAS_LABEL |
Yes, one of external_id or alias_name and alias_label |
These two columns create a user alias object. alias_name should be a unique identifier, and alias_label specifies the type of alias. Users may have multiple aliases with different labels, but only one alias_name per alias_label. |
PROPERTIES |
Yes | JSON string of fields to make available as personalization properties in your Canvas. This should contain user-specific information. |
To get started, select the Canvas Triggers data type when creating a new sync.
To delete user profiles in Braze using files in your source bucket:
- Create a new Cloud Data Ingestion sync, using the same setup as for other syncs.
- When configuring the sync in Braze, set Data Type to Delete Users.
- Upload files to your source bucket that contain only user identifier columns. Do not include a
PAYLOADcolumn—the sync fails if payload is present, to avoid accidental deletions.
Each row in the file must identify exactly one user using one of:
| Identifier | Description |
|---|---|
EXTERNAL_ID |
Matches the external_id used in Braze. |
ALIAS_NAME and ALIAS_LABEL |
Both columns together identify the user by alias. |
BRAZE_ID |
Braze-generated user ID (existing users only). |
JSON example
{"external_id":"user-to-delete-001"}
{"external_id":"user-to-delete-002"}
{"braze_id":"braze-id-from-profile"}
CSV example
external_id
user-to-delete-001
user-to-delete-002
When the sync runs, Braze processes new files in the bucket and deletes the corresponding user profiles.
Deleting users is permanent and cannot be undone. Include only users you intend to remove. For more details, see Delete users with Cloud Data Ingestion.
Deleting catalog items
To remove items from a catalog using file storage:
- Use the same sync you use to sync catalog data (data type Catalogs).
- In your CSV or JSON files, add an optional
deleted(orDELETED) column. - Set
deletedtotruefor any catalog item you want removed from the catalog in Braze.
Each row still needs ID and PAYLOAD. For rows marked for deletion, the payload can be minimal; Braze removes the item by ID.
When the sync runs, rows with deleted: true cause the matching catalog item to be deleted in Braze. For full catalog sync and delete behavior, see Sync and delete catalog data.
Things to know
- Files added to the source bucket or container should not exceed 512 MB. This limit applies to Amazon S3, Google Cloud Storage, and Azure Blob Storage. Files larger than 512 MB result in an error and are not synced to Braze. Azure Blob Storage itself allows much larger files, but CDI applies the same 512 MB limit across all file storage sources.
- While there is no additional limit on the number of rows per file, Braze recommends using smaller files to improve how fast your syncs run. For example, a 500 MB file would take considerably longer to ingest than five separate 100 MB files.
- There’s no additional limit on the number of files uploaded in a given time.
- Ordering isn’t supported in or between files. Braze recommends batching updates periodically if you’re monitoring for any expected race conditions.
- CDI only processes files that are added after the sync is created. You can use existing files to validate that Braze can access your bucket and detect files to ingest, but they are not synced to Braze. To have CDI process them, re-upload to the source bucket any existing files that you want synced.
Troubleshooting
Uploading files and processing
CDI only processes files uploaded after the sync is created. Each new blob triggers a Blob Created event to your queue. To ingest files that already exist in the container, re-upload them.
Handling unexpected file errors
If files aren’t ingested, verify the following:
- The event subscription exists on the storage account and is filtered to Blob Created.
- The event subscription uses Event Grid Schema. CDI can’t read events delivered in another schema.
- The event subscription’s endpoint points at the queue configured on the sync, not a different queue.
- The Braze service principal has Storage Blob Data Reader, Storage Queue Data Reader, and Storage Queue Data Message Processor on the storage account.
- The service principal’s client secret hasn’t expired. Azure enforces an expiry on client secrets, and an expired secret stops the sync.
For more information, see Azure Blob Storage as an Event Grid source in the Microsoft documentation.
Incorrect Integration Object error
This error occurs when two or more workspaces have integrations pointing to the same cloud storage bucket or folder. Each cloud storage location can only be used by one integration at a time. For resolution steps, see the FAQ.
Related pages
- Table setup for required columns and payload formatting
- Best practices for sync scheduling and data point efficiency
- Sync logs and observability for monitoring sync runs
- FAQ for common questions across all sources